Voice AI latency is the spec that decides whether a caller feels like they are talking to a person or waiting on a machine. You can have the best model and the nicest voice on the market, and a long pause after every sentence will still make the call feel broken.
Voice AI latency is the time between a caller finishing a sentence and the AI voice agent starting to reply. It is the sum of turn detection, speech-to-text, the language model, text-to-speech and the network. Streaming every stage, keeping prompts lean and running close to callers keeps it low.
This is the engineering companion to the complete guide to AI voice agents. If you want the business case, start there. If you want to know why some agents feel alive and others feel slow, read on.
The 200 millisecond instinct
Human conversation has a rhythm built into it. Across many languages, the typical gap between one speaker finishing and the next starting is around 200 milliseconds (Stivers et al., PNAS, 2009). That is faster than conscious thought. We do not decide to answer quickly; we just do, and we notice right away when someone does not.
That instinct is what your voice agent is judged against. The caller is not comparing it with last year's chatbot. They are comparing it, without thinking, with every phone call they have ever had. When the pause stretches toward a second or more, callers start to say "hello?" and talk over the agent, and a call that talks over itself goes downhill fast.
Where the delay comes from
A voice agent's reply is a relay race. Each stage hands off to the next, and the caller hears the total.
Where the milliseconds go on every turn
Turn detection
Deciding the caller has actually stopped talking

Speech to text
Turning the last words into text

Language model
Reading the conversation and writing a reply

Text to speech
Turning the first words of the reply into audio
Network and phone carrier
Every hop between the caller and the servers
| Stage | What adds delay | What cuts it |
|---|---|---|
| Turn detection | Waiting too long to be sure the caller stopped | Tuned end-of-turn detection, so the agent neither waits nor interrupts |
| Speech to text | Transcribing only after the caller finishes | Streaming transcription that works while they talk |
| Language model | Long prompts, big knowledge dumps, slow models | Lean prompts, targeted knowledge lookups, a fast model |
| Text to speech | Generating the whole reply before speaking | Speaking the first words while the rest is generated |
| Network | Servers far from your callers, extra hops | Running close to your callers and carrier |
The engineering choices that buy you speed
Stream everything
The slow design waits for each stage to finish before starting the next: hear the whole sentence, transcribe all of it, write the whole reply, then speak. Every "whole" in that sentence is a stall. The fast design overlaps the stages, so transcription runs while the caller is still talking and the voice starts on the first clause of the reply. StrideOps voice agents run on a streaming pipeline built on the open-source Pipecat framework for exactly this reason.
Keep the prompt lean
The model's time grows with how much it has to read and write on every turn. A bloated system prompt or a full price list pasted into the prompt slows every single reply. Put the facts in a knowledge base, look up only what the current question needs, and keep replies short. Short replies also sound more natural on the phone.
Pick providers for speed, per agent
Speech-to-text, model and voice providers are not equally fast, and the fastest is not always the right one for every agent. In StrideOps you choose the speech, model and voice provider for each agent, so a high-volume outbound agent and a careful booking agent can make different trade-offs.
Get turn detection right
Good turn detection is worth more than it looks. Cutting in early feels rude. Waiting too long feels slow. Neither problem shows up in an average latency number, which is why you have to listen to real calls.
Run close to the call
A round trip to a server on another continent is delay you can never get back. Ask any vendor where their voice pipeline runs relative to your callers and your phone carrier.
How to measure latency yourself
Do not take a vendor's number on faith, ours included. Measure it in an afternoon:
- Call the agent from a real phone, on a mobile network, not from a browser demo on office Wi-Fi.
- Record the call and open it in any audio editor.
- Measure the gap between the end of your last word and the start of the agent's first word, on at least 20 turns.
- Look at the slow turns, not the average. The first turn of a call, knowledge lookups and calendar checks are usually the slowest. Callers remember the worst pause, not the median.
- Interrupt it. Talk over the agent mid-sentence and check that it stops and listens.
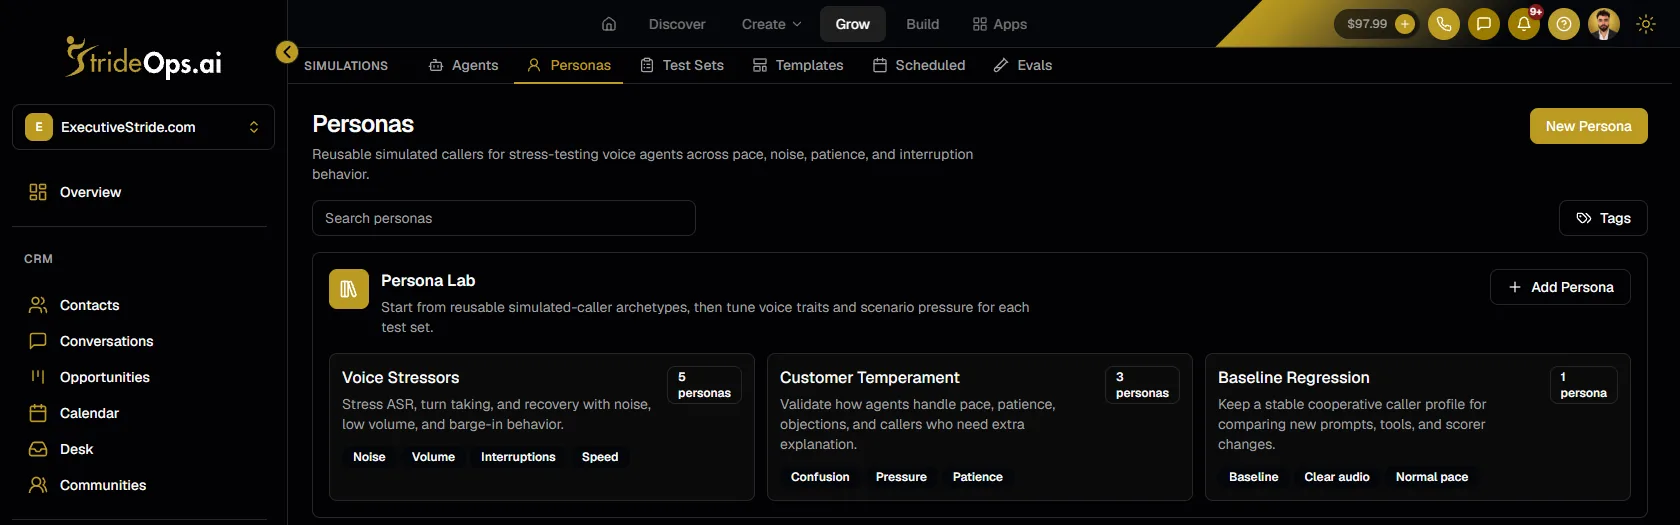
Then test the agent the way real callers will push it. StrideOps runs simulated callers with voice stressors (background noise, low volume, interruptions, fast talkers) and different temperaments, so you hear the slow and awkward moments before a customer does.
Why latency matters beyond the feel
- Completed calls. Callers who feel the lag hang up. Faster agents finish more conversations, which means more booked appointments. That flows straight into the math on what an AI receptionist costs.
- Trust. A responsive agent sounds competent. A slow one sounds broken, and callers stop giving it real information.
- Interruptions. Only a fast, streaming system can let a caller cut in and have the agent stop cleanly. That one behavior does more for "sounds human" than any voice model.
What to ask a voice AI vendor
- What are your median and slowest-case response times, measured end to end on real phone calls, first turn included?
- Where does your voice pipeline run, and how close is it to my callers?
- Can I hear a recorded call where the caller interrupts the agent?
- Can I choose the speech, model and voice providers myself?
A vendor that answers all four with specifics is doing the hard engineering. A vendor that answers with "lightning fast" is selling a demo.
FAQ
What is voice AI latency?
Voice AI latency is the delay between a caller finishing what they say and the AI voice agent starting its reply. It adds up across turn detection, speech-to-text, the language model, text-to-speech and the network.
What is a good latency for a voice AI agent?
There is no official threshold. Human turn-taking runs around 200 milliseconds, so the closer an agent gets, the more natural it feels. Long pauses of around a second or more are where callers start talking over the agent.
How do I reduce voice AI latency?
Stream every stage so they overlap, keep the prompt short and look up knowledge only when needed, pick fast speech and voice providers, tune turn detection, and run the pipeline close to your callers.
Why does my AI voice agent pause before answering?
The usual causes are a long prompt, a slow knowledge or calendar lookup during the turn, turn detection set to wait too long, or a slow speech or voice provider. Record a call and find which turns are slow to narrow it down.
The bottom line
Voice agents live and die in the moments after the caller stops talking. Measure that gap yourself on real phone calls, look at the slowest turns, and fix the stage that causes them. Then test with hard callers before real ones. See how StrideOps voice agents are built and tested.
Hear a voice agent on a real call
StrideOps voice agents run on a streaming pipeline with your choice of speech, model and voice providers, tested against simulated callers before they go live.
About the author
Josh Pocock
Founder & CEO, StrideOps.ai
Josh Pocock is the founder and CEO of StrideOps.ai. He spent eight years building sales and marketing companies - most recently Executive Stride, the AI appointment-setting agency that now runs end to end on StrideOps.ai as customer zero. He went all-in on the platform full-time in late 2025.
Josh Pocock is the founder and CEO of StrideOps.ai. He scaled his own AI agency past $50K a month, and his agency Executive Stride has built systems for 400+ businesses. StrideOps started as the platform he built to replace that stack.
Read more
After Hours AI Receptionist: Catch the Calls You Miss
After hours AI receptionist setup: answer every evening and weekend call, book the next open slot, route emergencies to on-call staff, and follow up by text.
AI Appointment Reminder Calls: Setup, Script and Timing
AI appointment reminder calls that confirm, catch reschedules and save no-shows: when to call, what the AI should say, and how to build it as one workflow.
AI Phone Agent for Car Dealerships: Sales and Service
AI phone agent for car dealerships: book service appointments, call internet leads in seconds, set test drives and run service and lease-end campaigns.